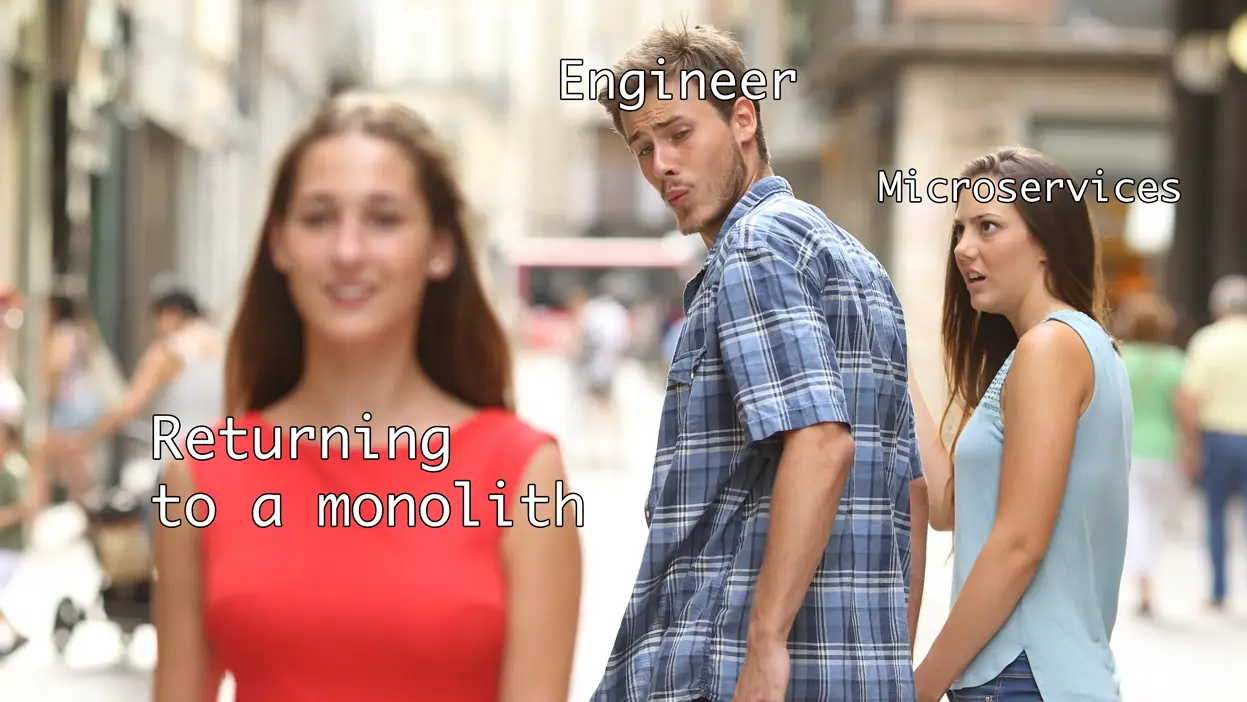
Somewhere along the way, microservices became the villain of modern software architecture. Every few months, a company announces it’s returned to a monolith, and the internet reacts like someone just came back from a silent retreat.
Fewer deployments, less infrastructure, fewer network calls, and fewer headaches. Congratulations, I guess. But I can't help wondering whether microservices were the problem, or whether the architecture was poorly designed from the start.
I've seen both sides. Monoliths aren't the magical simplicity machines people sometimes make them out to be, and I've watched microservices go horribly wrong. Services that started with a clear purpose slowly accumulated responsibilities until they became monoliths of their own, only now communicating over HTTP.
That's not an argument against microservices. It's an argument against ignoring boundaries.
I'm an advocate for microservices designed around Domain-Driven Design (DDD): services that represent real business capabilities, teams that deploy independently, and workloads that scale on their own terms. So before we declare the experiment a failure, let's talk about what actually goes wrong.
One Codebase, One Deployment, Everyone's Problem
Monoliths are cheaper to operate, and I'll give them that. One application is easier to deploy, monitor, and maintain than twenty, and you skip the service discovery, message brokers, and distributed tracing. But infrastructure isn't the only expense. Engineers cost money, too. So do delayed releases and the time spent untangling changes that have nothing to do with one another.
At a previous company (names withheld to protect the guilty), I saw firsthand what happens when a large engineering organization works in a shared codebase. Multiple teams are constantly pushing changes, each with different features, different bugs, and different deadlines. The commit volume alone is a challenge, but the real problems show up when something breaks.
Imagine spending several days building and testing a feature, only to discover that another team's changes have blocked the release. Your code works. Your tests pass. Your feature is ready. None of that matters, because everyone shares the same deployment unit.
Now the team has to find the offending change, decide whether a rollback is safe, and coordinate a fix, while other engineers keep merging code into an already complicated situation.
And we're calling this simpler?
Sure, there's only one application to deploy. There's also only one application that everyone depends on deploying successfully. Why should a team improving payment processing wait on a bug in a reporting feature? Why should a problem in one part of the business stop another from delivering value?
Yes, feature flags, trunk-based development, and solid CI/CD pipelines help, and a well-engineered monolith can absolutely support continuous delivery. If your company deploys a monolith fifty times a day, great. But none of that changes the fact that it's a shared deployment unit, and that matters more with every team and business domain you add.
The operational cost of a monolith might be lower. The organizational cost grows with the size of your engineering team.
Microservices Are About Boundaries, Not Endpoints
This is where a lot of microservice implementations go wrong.
Someone decides the application has gotten too large, so the team starts extracting functionality into separate services. They move some business logic into a new repository, put an API in front of it, and congratulate themselves on a shiny new architecture. But a new repository and a REST endpoint don’t create a meaningful service boundary. They just create a new place to put code.
A microservice should represent a specific business capability. That's why I'm such a strong advocate for DDD: it pushes engineers to understand the business domain, identify bounded contexts, and model software around the language and responsibilities of the business itself.
Consider a lending platform. Loan origination, underwriting, payments, and notifications are different capabilities with different workflows and potentially very different scaling needs. Those boundaries are a foundation for independently owned services. Underwriting shouldn't start sending marketing emails just because it already has customer data. And no service should need to understand another service's internal database structure to do its job.
DDD doesn't require microservices, by the way. You can implement bounded contexts inside a modular monolith, and understanding those boundaries before introducing distributed infrastructure is often the sensible move. But microservices let you take those boundaries further, turning them into boundaries for deployment, scaling, ownership, and operational responsibility, not just lines within a codebase.
That's the value I'm interested in.
Congratulations, You've Built Another Monolith
Now the other side of the problem, because I've seen microservices become a mess, too.
It usually starts innocently. A team creates a service for a particular domain. The API is small, the responsibilities are clear, and everything works beautifully. Then someone needs another endpoint. No problem. A few weeks later, another feature needs some additional functionality. That gets added, too. Eventually another team realizes the service already has the data they need, so they ask for an endpoint that doesn't quite belong there.
Before long, the service is the convenient place to put anything remotely related to its original purpose. Its API keeps growing. Its dependencies multiply. Its database accumulates tables that have little to do with the original domain. The team maintaining it becomes a bottleneck for everyone consuming it.
Sound familiar?
That's a monolith with a network connection.
If a service becomes a dumping ground, the problem isn't that it exists independently. Its boundaries were never properly established or maintained.
There's a worse variation: splitting an application into services that remain so tightly coupled they have to be changed and deployed together. If updating one service requires coordinated changes across six others, what exactly did you gain? You've kept the coupling of a monolith and added network latency, distributed failure modes, and more infrastructure to manage. That's a distributed monolith, no matter how many repositories or Kubernetes pods you've created.
The answer isn't necessarily to shove everything back into one application. It's to understand why the services are coupled and whether their boundaries reflect the actual business domain. Sometimes responsibilities need to move. Sometimes a service needs to be split. Sometimes two services that constantly change together should be one. A microservice isn't successful because it's small. It's successful because it has a cohesive responsibility and can evolve without dragging unrelated parts of the system along.
Scaling Everything Because One Thing Is Busy
A monolith can scale. Of course it can. Decades of successful applications running behind load balancers prove it. But being able to scale something and being able to scale it efficiently are two different things.
Imagine an application handling authentication, customer management, reporting, document processing, and transaction processing. Most of those see predictable traffic, but document processing occasionally eats substantial CPU and memory. In a conventional monolithic deployment, scaling that workload can mean running more instances of the entire application, paying for resources that most components don't need.
With independently deployed services, you scale document processing according to its actual demand and leave everything else alone. Monoliths can soften this with background workers and separate process types, but once you're separating workloads operationally, you're already admitting that different parts of the application have different needs. Microservices take that separation further, giving each capability its own runtime configuration, scaling policy, and deployment lifecycle.
This doesn't automatically make microservices cheaper. A poorly designed architecture can spend more on network communication and orchestration than it saves through targeted scaling. But at sufficient scale, with workloads that vary significantly, allocating resources precisely where they're needed is extremely valuable.
Your Team Shouldn't Need Permission to Deploy
One of the biggest benefits of microservices has very little to do with technology. It's team autonomy.
When services are designed around real business domains and owned by teams that understand them, engineers can make changes without coordinating with the entire organization. Shared contracts and cross-domain changes still require conversation, and microservices don't magically eliminate organizational dependencies. But they can eliminate the unnecessary ones.
This is where architecture and team structure collide. If every service is owned by a different team but every change needs approval from five others, you haven't achieved autonomy. You've distributed the bureaucracy. And if one team owns twenty services and becomes responsible for every feature the rest of the company requests, you've built a bottleneck out of smaller parts.
Service ownership needs to match the responsibilities of the teams maintaining it. Otherwise the architecture looks distributed while the organization keeps operating as though everything belongs to one giant application. That's why I think microservices and DDD belong together: you're not arbitrarily dividing code, you're drawing boundaries that make sense both technically and organizationally.
Microservices Aren't an Excuse to Skip Engineering Discipline
None of this means microservices are easy.
Network calls fail. Messages arrive late or twice. Services go down. Transactions that were trivial inside one database suddenly require careful thought about consistency and recovery. Observability becomes essential, API contracts need maintaining, backward compatibility matters, and deployment automation becomes more important, not less.
That's the trade-off. But complexity doesn't disappear when you choose a monolith. It shows up somewhere else: a tangled dependency graph instead of distributed tracing, coordinated changes to shared tables instead of coordinated API contracts, one pipeline every team depends on instead of many.
The question isn't which architecture has zero complexity. Neither does. The question is which complexity you're willing to manage and what you get in return. For a small application maintained by a handful of engineers, ten microservices might be an absurd decision. For a large organization with distinct domains, varied workloads, and multiple teams trying to deliver independently, I believe they're a much better foundation, on one condition: you design them properly.
A service needs a clear purpose, explicit data ownership, an API that exposes capabilities rather than leaking implementation details, and a team willing to push back on responsibilities that don't belong. And architecture isn't finished when the migration is. Domains evolve, and boundaries that made sense two years ago might not make sense today. A healthy architecture means continuously re-evaluating them.
Stop Blaming Microservices for Bad Architecture
I'm not arguing that every application should use microservices. That would be as ridiculous as arguing every application should be a monolith. What I object to is treating failed microservice implementations as proof the whole approach is broken.
If your services share one giant database, require coordinated deployments, expose endless unrelated endpoints, and can't function without synchronous calls to half the organization, then yes, you've probably built a distributed monolith. A monolith isn't automatically simpler just because it lives in one repository, and microservices aren't automatically better just because they live in twenty.
So if you've spent the last year breaking your monolith into services, only to find that deployments still require a company-wide meeting and every feature touches six different APIs, I have some unfortunate news.
Congratulations. You've built a distributed monolith.
But don't blame microservices. Blame the boundaries you forgot to respect.